A DNA Likelihood Is Not a Functional Assay: Genomic Foundation Models in 2026
The ticket says: “Run the best genomic foundation model on chr12:34,567,890 A>G and predict the effect.”
It looks executable. It is not. chr12 does not identify an assembly or coordinate convention. The allele has no declared strand. The ticket omits the surrounding window, cell type, assay, and endpoint. “Effect” might mean an alternate-allele probability, a sequence-likelihood difference, a frozen embedding passed to a classifier, or a change in a supervised regulatory track. Four numbers may emerge. They do not measure the same thing.
There is no evaluation split either, so success itself is undefined. The software may run. The experiment has not yet been specified.
Part 4, An Antibody Sequence Is Not a Research Plan made the experimental contract the first modelling decision. Genomics needs the same discipline, with extra failure modes from coordinate systems, two sequence orientations, overlapping windows, evolutionary redundancy, and assay-specific outputs.
This guide starts with the biological question and the evidence needed to answer it. It moves from input representation to strand, context, training prior, supervision, split, and usable artifacts. Model families appear only when they change one of those decisions.
Figure 1. A genomic request becomes executable only when coordinate identity, biological target, model output, adaptation, and split are explicit. Systems that require an alignment or supervised assay output need more than a sequence window.
Sources: GPN-MSA documentation, Enformer, BEND, and the unreviewed DART-Eval version 2 preprint.
Will one nucleotide remain one edit?
Before comparing architectures, tokenise the reference and alternate sequences. That unit test can invalidate the proposed score before a model is loaded.
The model families make different trade-offs. Treat these as input contracts, not as a leaderboard.
| Family | Token unit | Where one edit lands | Crop sensitivity | Consequence for a score |
|---|---|---|---|---|
| DNABERT | Overlapping fixed-length k-mers | Every k-mer spanning the edited base can change | Crop and special-token handling determine the available input positions | A substitution changes a neighbourhood of model tokens, not one isolated input |
| DNABERT-2 | Byte-pair encoding (BPE) | An edit can change nearby token boundaries | The local segmentation can change with sequence context | Token-level reference and alternate scores may no longer align one-to-one |
| Nucleotide Transformer v1/v2 | Non-overlapping 6-mers | One six-base token changes for a fixed crop | Moving the crop origin changes the six-base grouping | Report crop origin and score both alleles under the same phase |
| NTv3 | Single bases | The substitution remains one input position | Long windows still require an explicit crop | Keep pre-trained, post-trained, and generative checkpoint results separate |
| HyenaDNA, Caduceus, and Evo | Single bases | The substitution remains one input position | Context selection still determines what the model sees | A clean edit boundary does not prove better biological inference |
| GENERator-v2 | 6-mers | The edited base changes its containing token | The official card expects lengths divisible by six | Its nucleotide-level likelihood objective changes scoring, not tokenisation |
Two quick allele tests make the distinction concrete:
- Overlapping k-mers: run the same
A>Gsubstitution through the DNABERT tokenizer. Compare the full reference and alternate token lists. Every k-mer that spans the locus can change, so “one variant” is not “one changed token.” DNABERT's published 512-position maximum is also a limit after k-mer conversion and special-token handling, not an unqualified 512-base window. - Non-overlapping 6-mers: run the allele pair through Nucleotide Transformer twice, shifting the crop origin for the second run. The edit remains inside one token in each run, but the token's other five bases can differ because the phase changed. A score that moves with that shift is crop-sensitive, even though the biological variant did not move.
The release details still matter. DNABERT-2 also moves to multispecies training and a changed benchmark setup; its paper describes 36 datasets across nine tasks while the current repository retains an older 28-dataset, seven-task description (DNABERT-2 repository). Nucleotide Transformer spans 50 million to 2.5 billion parameters and human-reference, population, and 850-species checkpoints; the inspected NT-v2 card uses 2,048 token positions and exposes logits and embeddings separately (NT-v2 500M model card).
NTv3's developers report a U-Net-like architecture, contexts up to one megabase, and post-training with roughly 16,000 functional tracks and annotations from 24 species. These remain developer-reported claims in an unreviewed preprint, and the official guide lists pre-trained, post-trained, and generative branches separately. Likewise, GENERator-v2's proposed Factorized Nucleotide Supervision obtains nucleotide-level likelihoods from coarse tokens; it does not replace the input tokenizer (Li et al., 2026, preprint).
Figure 2. Tokenisation fixes the edit boundary; the output type fixes the reverse-complement relationship. The four token contracts and strand strategies are documented by DNABERT, DNABERT-2, the NT-v2 card, GENERator-v2, Caduceus, and the unreviewed reverse-complement consistency preprint.
Never call a variant “one-token” until the actual tokenizer proves it. Record raw bases, model tokens, special tokens, crop origin, padding, ambiguous-base handling, and both allele token sequences. “Same context length” is otherwise not the same experiment.
What should reverse complementation do to the answer?
The same double-stranded locus can be presented in two orientations. The required output relationship depends on the task. An unoriented classifier may require invariance. A nucleotide profile must reverse positions and may need its strand channels swapped. A directional transcription output can be genuinely strand-specific.
Caduceus exposes two architectural choices. Caduceus-Ph is not inherently reverse-complement equivariant and is pretrained with reverse-complement augmentation. Caduceus-PS builds that equivariance into parameter sharing and does not require augmentation for the property (Caduceus release). They are parallel symmetry variants, not versions. The released 131k cards refer to single-nucleotide sequence length; d_model=256 is hidden width, not a parameter count (Caduceus-Ph card; Caduceus-PS card).
Equivariance guarantees a transformation property, not task accuracy. An unreviewed 2025 preprint reports that reverse complementation can alter outputs from Nucleotide Transformer, HyenaDNA, and DNABERT-2 backbones, and proposes RCCR fine-tuning for classification, scalar regression, and profile heads (Ma, 2025, preprint). That is developer-reported evidence on selected tasks. The reusable test is simpler: run both orientations through tokenisation, pooling, and the final head, transform the output as the label requires, and publish the discrepancy before any aggregation.
Strand consistency belongs in evaluation, not in a model-name assumption.
Can the model use the bases it can accept?
Maximum context is a capacity figure. Useful context is an experimental result.
HyenaDNA’s authors report single-nucleotide contexts up to one million tokens and subquadratic sequence scaling. The base checkpoints were pretrained on the single human reference genome hg38; the authors' speed comparison depends on the selected transformer baseline and hardware (Nguyen et al., 2023; HyenaDNA release). That establishes a long input path, not a million bases of useful regulatory dependence.
Evo 1 uses an autoregressive next-token objective and a 131,072-token StripedHyena context. Its 7-billion-parameter release was trained on roughly 300 billion prokaryotic OpenGenome tokens (Nguyen et al., 2024; OpenGenome). Evo 2 extends the programme to StripedHyena 2, OpenGenome2 across all domains of life, and checkpoint variants up to one million base pairs (Brixi et al., 2026; Evo 2 release). The generations differ in objective implementation, corpus, context curriculum, checkpoint sizes, and hardware. Their results are not exchangeable.
Regulatory endpoints need a comparison with supervised sequence-to-function specialists. Enformer takes 196,608 bases and predicts the central 114,688 bases in 128-base bins. Its 2021 evaluation used measured CAGE, accessibility and ChIP-seq tracks, with Basenji2 compared on the same data; the held-out genomic regions do not constitute unseen-cell-type validation. Its peer-reviewed paper reports integration of interactions up to 100 kb away within that assay-conditioned setup (Avsec et al., 2021).
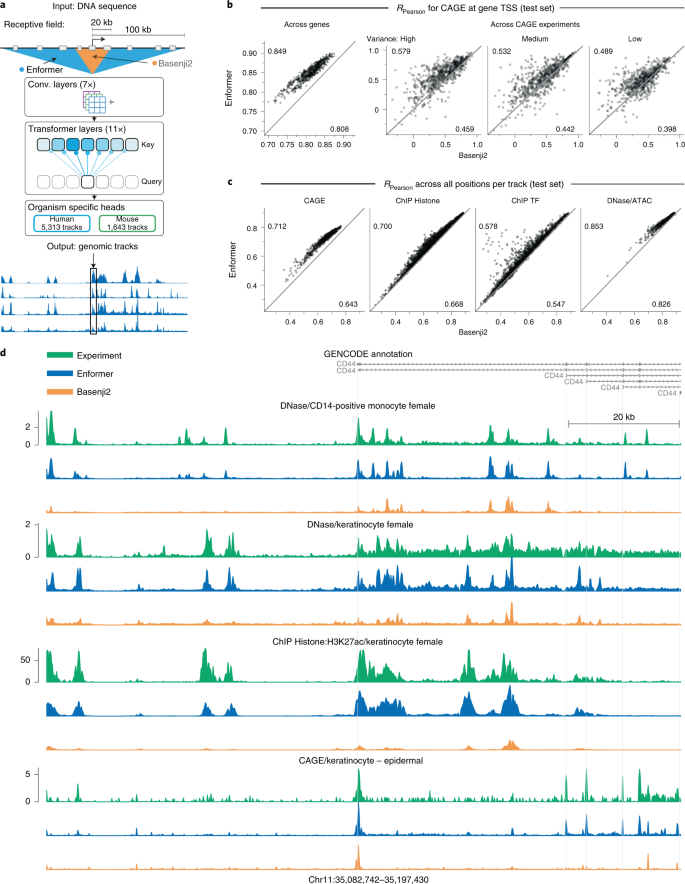
Figure 3. Enformer connects a long sequence window to named supervised assay outputs. Figure 1 from Avsec et al. (2021), unmodified, licensed under CC BY 4.0.
Borzoi chooses a related but distinct contract: 524 kb inputs and 32-base output bins for cell- and tissue-specific RNA-seq coverage. Its authors also report that tissue-specific alternative splicing was not learned well in their setup (Linder et al., 2025). A long supervised input supported some outputs and missed another. That is more informative than the window size by itself.
A useful practical evidence ladder starts with capacity and ends with intervention. A successful forward pass establishes capacity. Synthetic recall establishes that information can survive the architecture. Perplexity establishes distribution modelling. A distal ablation on the target endpoint tests task-relevant dependence. A prospective perturbation can test whether that dependence follows an intervention. Do not climb from the first rung to the last in one sentence (HyenaDNA; Enformer; Borzoi).
A control that keeps local sequence intact
Here is a proposed experiment, not a model result. Start with 131,072-base windows centred on a transcription start site and a declared expression endpoint. Preserve the central 8,192 bases. Divide each 61,440-base flank into sixty 1,024-base chunks, then permute those chunks separately within each flank using seeds 17, 29 and 43. Sequence inside each chunk, total base composition and the focal window survive; distal order, distances to the focal site and some boundary-spanning motifs do not.
Evaluate the original and shuffled windows with the same fitted predictor, frozen head and held-out loci. Report the paired change in Spearman correlation with measured expression, with uncertainty resampled by gene, and prediction changes per locus. Compare against an 8,192-base local model and a local one-hot or k-mer baseline fitted with the same training/validation/test assignments and tuning budget. A shorter input needs its own declared training protocol; silently resizing a trained head changes the comparison.
Use a second control that shuffles bases inside distal chunks to distinguish dependence on chunk order from dependence on their internal motifs. Include repeated unmodified inference as a no-perturbation control. Repeat the analysis in strata of repeat content and with several chunk sizes. These are proposed diagnostic choices, informed by Enformer's receptive-field ablation in Extended Data Fig. 5b and DART-Eval's composition-matched controls; neither paper establishes these exact settings as a standard.
Artificial rearrangements can move sequences outside the training distribution. A performance drop therefore shows sensitivity to the perturbation, not necessarily correct use of a distal regulatory mechanism. An unchanged result can also reflect redundant information or a weak test. Follow up on specific loci with relevant perturbation measurements before making a mechanistic claim.
The accompanying control generator runs on a FASTA sequence and records the chunk permutations and hashes. Its bundled synthetic example tests sequence bookkeeping only; no genomic model was run for this illustration.
# Supply one declared TSS-centred FASTA record of exactly 131,072 bases.
python3 distal_shuffle.py --fasta tss-window.fa --out context-controls
# Or exercise the bookkeeping on synthetic input, without a model.
python3 distal_shuffle.py --synthetic --out synthetic-controls
Which distribution and objective supplied the prior?
A corpus defines familiarity. An objective defines the cheap way to reduce loss. Neither guarantees transfer.
Original DNABERT, released HyenaDNA bases, and released Caduceus checkpoints use human-reference pretraining rather than population or multispecies sequence (Ji et al., 2021; HyenaDNA release; Caduceus-Ph card). DNABERT-2 moves to multispecies training, while Nucleotide Transformer provides human-reference, population, and 850-species branches (Zhou et al., 2024; Dalla-Torre et al., 2025). Those corpora encode different priors. Species count is not a monotonic quality metric.
GPN narrows the evolutionary question. The original single-sequence GPN learns from unaligned genomes and was demonstrated for Arabidopsis variants using related Brassicales species (Benegas et al., 2023). GPN-MSA consumes a multispecies whole-genome alignment at inference. Its checkpoint and data store must agree on assembly, species count, species order, and preprocessing; current project documentation retains inference assets but says the training path is not maintained and recommends GPN-Star (GPN-MSA documentation). GPN and GPN-MSA do not share the same input contract.
GenNA changes the prior again by placing nucleotide sequence, natural-language descriptions, species metadata, and structured annotations in one autoregressive stream. Its unreviewed 2026 preprint reports 2,221 eukaryotic species and about 416 billion characters (Shen et al., 2026, preprint). The reported semantic-mismatch and perplexity tests are developer-run, in silico evidence. Annotation consistency does not establish that a generated sequence performs the described function.
The objective boundary matters just as much:
- Masked encoders learn conditional token recovery from both sides of a gap. Their likelihoods and embeddings reflect that reconstruction objective (Ji et al., 2021; Dalla-Torre et al., 2025).
- Autoregressive systems such as Evo learn next-token prediction from a serialized prefix and can generate sequence. Their likelihood remains a score under that direction and distribution (Nguyen et al., 2024).
- Supervised systems such as Enformer and Borzoi optimise named experimental tracks. Their outputs inherit the cells, assays, target definitions, and biases of those labels (Avsec et al., 2021; Linder et al., 2025).
- Hybrid NTv3 post-training intentionally crosses the boundary from masked sequence modelling to supervised tracks and annotations. Name the pre-trained or post-trained checkpoint when reporting a result (Boshar et al., 2025, preprint).
The families discussed above line up as follows. Read it as a map of priors, not a ranking.
| Model family | Input tokenisation | Context | Pretraining objective | Training prior and corpus |
|---|---|---|---|---|
| DNABERT | Overlapping k-mers, 3 to 6 | 512 tokens | Masked token recovery | Human reference (hg38) |
| DNABERT-2 | Byte-pair encoding | 512-token pretraining window; ALiBi replaces learned positional embeddings, so longer inputs are an extrapolation rather than a supported ceiling | Masked token recovery | Multispecies genome collection |
| Nucleotide Transformer v2 | Non-overlapping 6-mers | 2,048 tokens, about 12 kb | Masked token recovery | Separate branches: human reference, 3,202 human genomes, or 850 species |
| Caduceus | Single nucleotide | 131,072 bases | Masked bidirectional state-space modelling | Human reference (hg38); PS is RC-equivariant, Ph uses RC augmentation |
| HyenaDNA | Single nucleotide | Up to 1,000,000 bases | Causal next-token prediction over long convolutions | Single human reference (hg38) |
| Evo and Evo 2 | Single nucleotide | 131 kb (Evo), 1 Mb (Evo 2) | Causal next-token prediction | OpenGenome (Evo), OpenGenome2 (Evo 2) |
| GPN-MSA | Single base plus aligned species column | Alignment window, 512 bases | Masked recovery conditioned on the alignment | Multispecies whole-genome vertebrate alignment |
| Enformer and Borzoi | Single base, one-hot | 196 kb (Enformer), 524 kb (Borzoi) | Supervised regression onto named tracks | Human and mouse epigenetic and RNA-seq tracks |
Table: tokenisation, context, objective and corpus for the families named in this section. Sources are the same as the prose above: Ji et al., 2021; Zhou et al., 2024; Dalla-Torre et al., 2025; Caduceus-Ph card; HyenaDNA release; Nguyen et al., 2024; GPN-MSA documentation; Avsec et al., 2021; Linder et al., 2025. Context figures describe the released checkpoints named here, not every variant a project has published.
Match the holdout to the proposed transfer. A chromosome holdout asks about new coordinates under a related distribution. A species or phylogenetic holdout asks about evolutionary transfer. A temporal holdout asks about future records only when corpus and benchmark snapshots are dated. “Multispecies” without a transfer test is a training-data label, not evidence of generalisation.
Is the model zero-shot, or is only the backbone frozen?
Evaluation terminology can hide more supervision than architecture diagrams reveal.
True zero-shot scoring applies a prespecified rule without fitting a task head. A masked model may compare alternate and reference probabilities at a locus. A causal model may compare normalised sequence likelihoods. Those are measurements of compatibility with a learned sequence distribution; neither becomes a functional assay by naming it a variant score (Benegas et al., 2023; Jiang et al., 2026).
A frozen-embedding experiment is different. The backbone stays fixed, but labels train a probe or downstream head. Layer choice, pooling, head capacity, optimiser, and split can all affect the final result. A peer-reviewed 2025 benchmark calls its extracted representations “zero-shot embeddings,” then trains supervised classifiers after pooling. Its authors report that mean token pooling improved sequence classification over other pooling choices in that protocol (Feng et al., 2025). That is evidence about a frozen representation and trained head, not label-free task prediction.
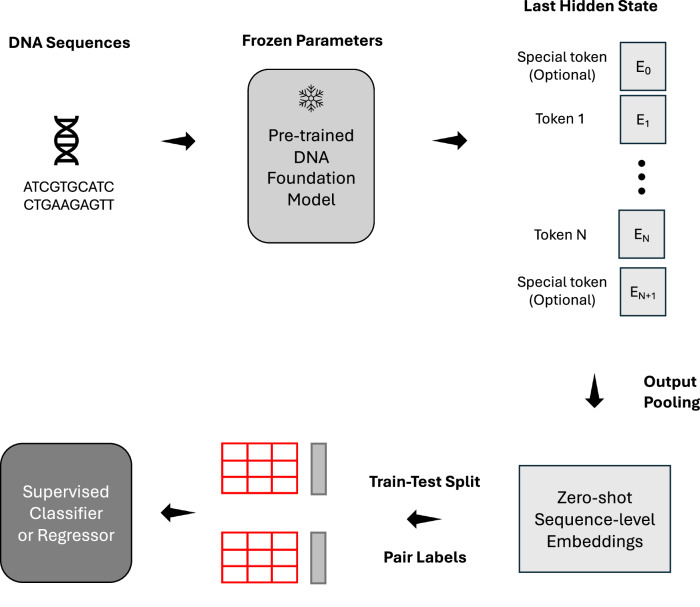
Figure 4. Frozen representation extraction is followed by pooling and a supervised task head. Figure 1 from Feng et al. (2025), unmodified, licensed under CC BY 4.0.
Use four explicit result labels:
- Untouched scoring: no task labels update a model or head.
- Frozen probe: the backbone is fixed while a labelled head is trained.
- Fine-tuning: labelled data update some or all backbone parameters.
- Supervised sequence-to-function: experimental tracks train the biological output directly.
For a controlled representation comparison, fix the extraction layer, pooling, head, label count, hyperparameter budget, and split. Sweep plausible layers rather than assuming the final layer is intrinsically best. For a best-system comparison, tune each model appropriately and say that the result compares complete systems. These are both useful experiments. Mixing them produces an impressive but uninterpretable table.
DART-Eval makes the separation visible across regulatory tasks. Its authors compare zero-shot, probing, fine-tuning, and ab-initio supervised baselines. In the retrieved unreviewed arXiv version 2 preprint, they report that simpler supervised models match or exceed larger fine-tuned DNA language models on several tested tasks, and that the tested language models perform poorly on their counterfactual tasks (Patel et al., 2025, unreviewed preprint). These are developer-reported conclusions within the benchmark's tested systems and implementations, not a universal ranking.
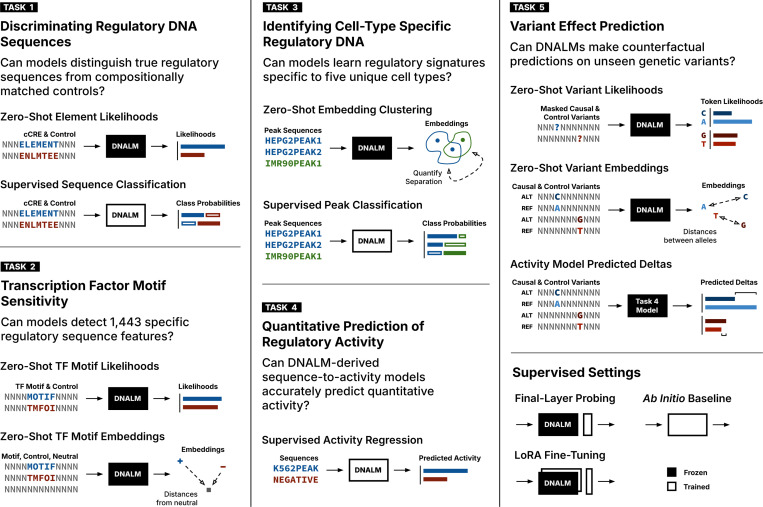
Figure 5. DART-Eval keeps adaptation regime, task type, and specialist baselines visible. Figure 1 from Patel et al. (2025), unmodified, licensed under CC BY 4.0. The source is an unreviewed arXiv version 2 preprint.
Variant scores need one more field: the operator. Masked log odds, causal sequence-likelihood ratios, embedding distances, alignment-conditioned evolutionary scores, and changes in supervised assay tracks have different units and assumptions (GPN; Evo; BEND; GPN-MSA; Enformer). Do not transfer thresholds or calibration across them without new validation. Report the checkpoint, objective, layer, pooling, head, label budget, split, and scoring operator beside every result.
Which claims does the evidence support?
For motif and sequence classification, the evidence supports specific transfer protocols. DNABERT reports fine-tuned downstream classifiers, Nucleotide Transformer reports low-cost fine-tuning, and Feng and colleagues evaluate frozen representations followed by supervised heads (Ji et al., 2021; Dalla-Torre et al., 2025; Feng et al., 2025). A good score can justify that backbone, extraction recipe, head, and split. It does not isolate an intrinsic, task-independent representation quality.
For variant effects, untouched masked or causal scores are testable hypotheses about a learned sequence distribution. GPN demonstrates a species-specific evolutionary scoring route from unaligned related genomes, while GPN-MSA requires an aligned multispecies input and publishes a separate human variant-scoring contract (Benegas et al., 2023; Benegas et al., 2025). These results support evaluation against population, association, or curated variant evidence in their stated settings. The GPN paper also says experimental validation of causal variants remains the gold standard.
For assay-defined outputs, supervised specialists provide the most direct evidence. Enformer predicts measured human and mouse tracks, Borzoi predicts RNA-seq and regulatory coverage, and AlphaGenome predicts multiple regulatory modalities under supervised training (Avsec et al., 2021; Linder et al., 2025; AlphaGenome, 2026). Their outputs remain bounded by cell types, assays, targets, and splits.
For generation, Evo, GENERator, and GenNA support sampling from different learned distributions, with different tokens, species coverage, and conditioning (Nguyen et al., 2024; Li et al., 2026, preprint; Shen et al., 2026, preprint). Likelihood, motif recovery, or semantic agreement can filter samples computationally. Functional language requires a separately specified validation stage.
Two questions that need different experiments
The following designs are hypothetical. They specify what to measure without inventing a model score or experimental outcome.
| Step | Regulatory question | Variant-interpretation question |
|---|---|---|
| Biological question | Does changing a candidate regulatory base alter reporter expression in unstimulated HepG2 cells? | Does an intronic variant alter inclusion of a specified exon in a declared transcript? |
| Model output | Reference-to-alternate change in a named HepG2 regulatory track; keep a DNA likelihood score as a separate comparator | A specialist splice score, compared with a separately defined DNA-model score; neither is a pathogenicity probability |
| Experimental endpoint | RNA-to-DNA reporter abundance, relative to the reference construct, at one fixed collection time | Reference and alternate minigene exon-inclusion measurements in HEK293T, with junction identity checked; patient RNA in a relevant expressing tissue answers a separate question |
| Comparison and controls | Identical vector and insert length, matched transfection conditions, independent replicates, inactive and known-active controls | Matched constructs and culture conditions, replicate measurements, splice-disrupting and reference controls; record transcript expression and any treatment affecting RNA decay |
| Defensible conclusion if confirmed | The base changes this reporter's activity under these conditions | The variant changes splicing in this assay; the gene–disease mechanism and clinical classification still need separate evidence |
These designs draw on the reporter measurements in Kircher et al. and the minigene approach in Cheung et al.. A HepG2 track and a HepG2 reporter still measure different endpoints: justify the track-to-reporter mapping and, if fitted, calibrate it on separate training loci. Neither assay transfers automatically to a different cell state or to the endogenous locus. For a clinical interpretation, follow the applicable gene-specific guidance: ClinGen's splicing recommendations distinguish computational predictions, RNA evidence and downstream functional assays. An altered reporter or splice product alone does not classify a patient's variant.
What an experimental comparison actually showed
Kircher and colleagues measured LDLR promoter substitutions in HepG2 cells using independently constructed reporter libraries. For c.-142C>T, they reported 20% and 11% residual promoter activity in the two libraries. This is a measured regulatory endpoint, not a DNA-model likelihood. For TERT c.-124C>T, the measured log2 change was 2.00 in HEK293T and 2.86 in glioblastoma SF7996 cells; these are log2 effects, not ordinary fold changes (LDLR and TERT results).
Enformer's developers subsequently compared predictions with the saturation-mutagenesis measurements. Their LDLR example captured two of four binding-site patterns well and detected another more weakly. Figure 4c lets you inspect both agreement and missed effects; it does not show perfect recovery. The comparison used Enformer and deltaSVM outputs without locus-specific additional training, while other rows in Figure 4a used fitted regressions (Avsec et al., Fig. 4).
Read the result beside its scope
| Evidence | Exact place to inspect | What it supports, and what it leaves open |
|---|---|---|
| BEND: computational evaluation using annotations, assay-derived labels and curated variants | Table 3 and Appendix A.1 | Frozen embeddings plus supervised CNN heads for annotation tasks; cosine-distance scoring for variant tasks. Metrics and splits differ by task. A ClinVar label is not a new functional experiment. |
| DART-Eval v2: regulatory benchmark | Table 6, Tables S19–S20 and July 2025 corrigendum | caQTL/dsQTL comparisons separate zero-shot, probe and fine-tuned methods from ChromBPNet. Use corrected allele orientation and peak definitions. Association labels and counterfactual assay predictions answer different questions. |
| GUE: developer benchmark for DNABERT-2 | Paper and dataset release | Supervised task performance under the named release; pin its data and split files. The repository's older seven-task description must not be silently combined with the expanded paper. |
| Saturation-mutagenesis measurements | Kircher et al., LDLR results and Fig. 1 | Observed reporter activity, including replicate variation; a construct in a cell line does not reproduce every endogenous regulatory condition. |
| Model versus those measurements | Enformer Fig. 4 | Developer-reported correlations on CAGI5 held-out variants at 15 loci; compare like adaptation regimes. This is retrospective prediction of assay effects. |
This is a selected evidence map, not an exhaustive benchmark survey. The model families, Wang comparison and Nullsettes stress test discussed elsewhere remain relevant to their own endpoints. The missing connection in this article was a traceable experimental example, not the mere presence of benchmark names. My interpretation is that a useful gain should survive the relevant baseline and change a declared experimental decision; a higher aggregate score alone does not demonstrate clinical utility.
What did the test set actually exclude?
“Held out” is not a biological property.
Genomic windows can overlap. Nearby loci share sequence and assay context. Reverse complements duplicate content. Homologous regions cross chromosomes and species. Population data can contain related haplotypes. A row-level random split can retain those relationships while looking statistically tidy. BEND supplies explicit split fields, but a split column proves only that rows were assigned somewhere (BEND repository). The unreviewed DART-Eval benchmark likewise shows why task, adaptation regime, and baseline must remain attached to a split-specific result (Patel et al., 2025, preprint).
Choose the exclusion that matches deployment. Use non-overlapping coordinate blocks or chromosomes to reduce local leakage. Cluster homologous sequence before splitting when the claim is family novelty. Hold out a species or clade for phylogenetic transfer. Use a temporal split for future data only if the model corpus and benchmark releases have known dates. Group donors, perturbation families, and experimental batches when they structure assay labels. These are study-design recommendations; each supports a different sentence in the conclusion.
Corpus overlap is broader than exact duplicate strings. Sequence sources can be updated after a benchmark's nominal date, and annotation-rich post-training can expose related targets. Archive the corpus snapshot, compare accession dates and coordinate ranges, search exact and reverse-complement matches, and mark homology or annotation checks that cannot be completed. Unresolved contamination is a result to report, not a blank to hide.
The downstream pipeline can add another source of variance. A 2025 preprint reports that BEND head-training scores changed with data-loader workers and shuffle buffers because genomic examples were autocorrelated in storage order (Greco and Rawlik, 2025, preprint). That finding is implementation-specific. It does show that fixed seeds without fixed example order and software versions are incomplete reproduction metadata.
Counterfactual sequences attack a different shortcut. Nullsettes creates in silico rearrangements of key regulatory elements in synthetic expression cassettes. The authors define the resulting virtual mutants as loss-of-function under canonical transcription and translation ordering constraints, then compare mutant and nonmutant likelihood distributions (Jiang et al., 2026).
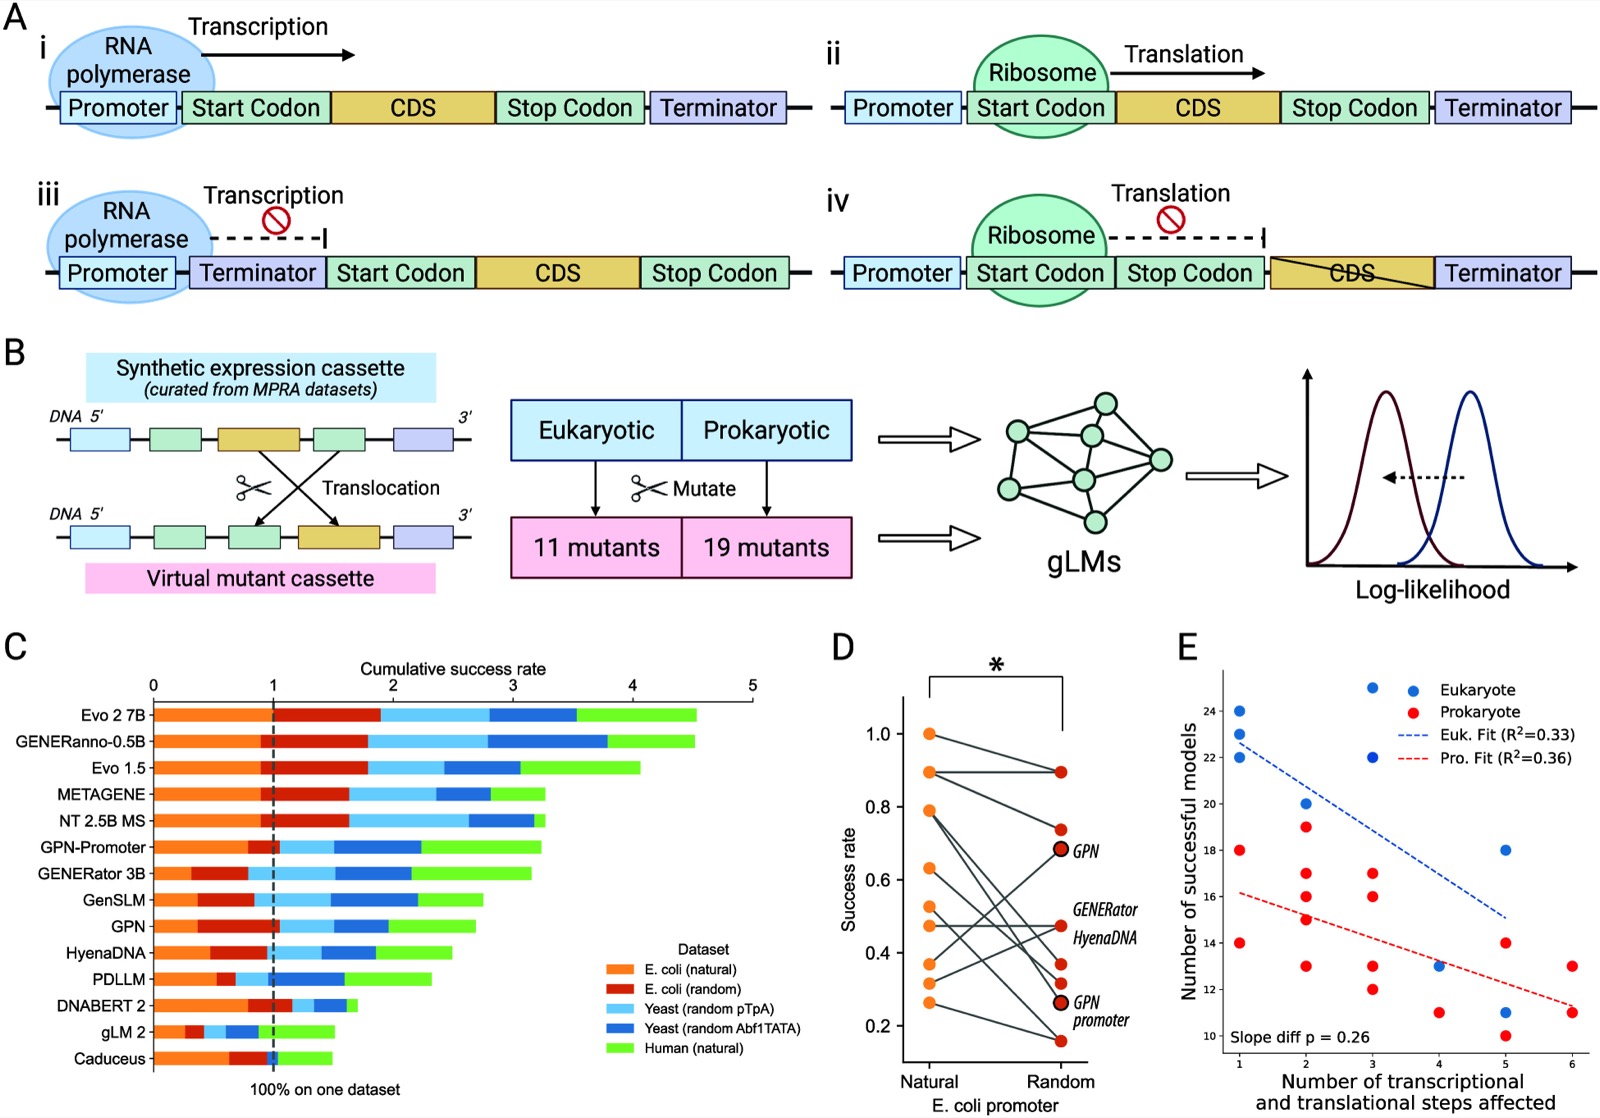
Figure 6. Nullsettes tests mutation-effect likelihood under deliberate distribution shift. Figure 1 from Jiang et al. (2026), uniformly resized from 3,900 × 2,725 pixels to 1,600 × 1,118 pixels, with no crop or content change, licensed under CC BY 4.0.
The peer-reviewed study reports frequent failures among most tested genomic language models, while also reporting Evo2-7B and GENERanno-0.5B as strong, consistent performers. Across the tested models, accuracy declines as the intact sequence receives lower model likelihood (Jiang et al., 2026).
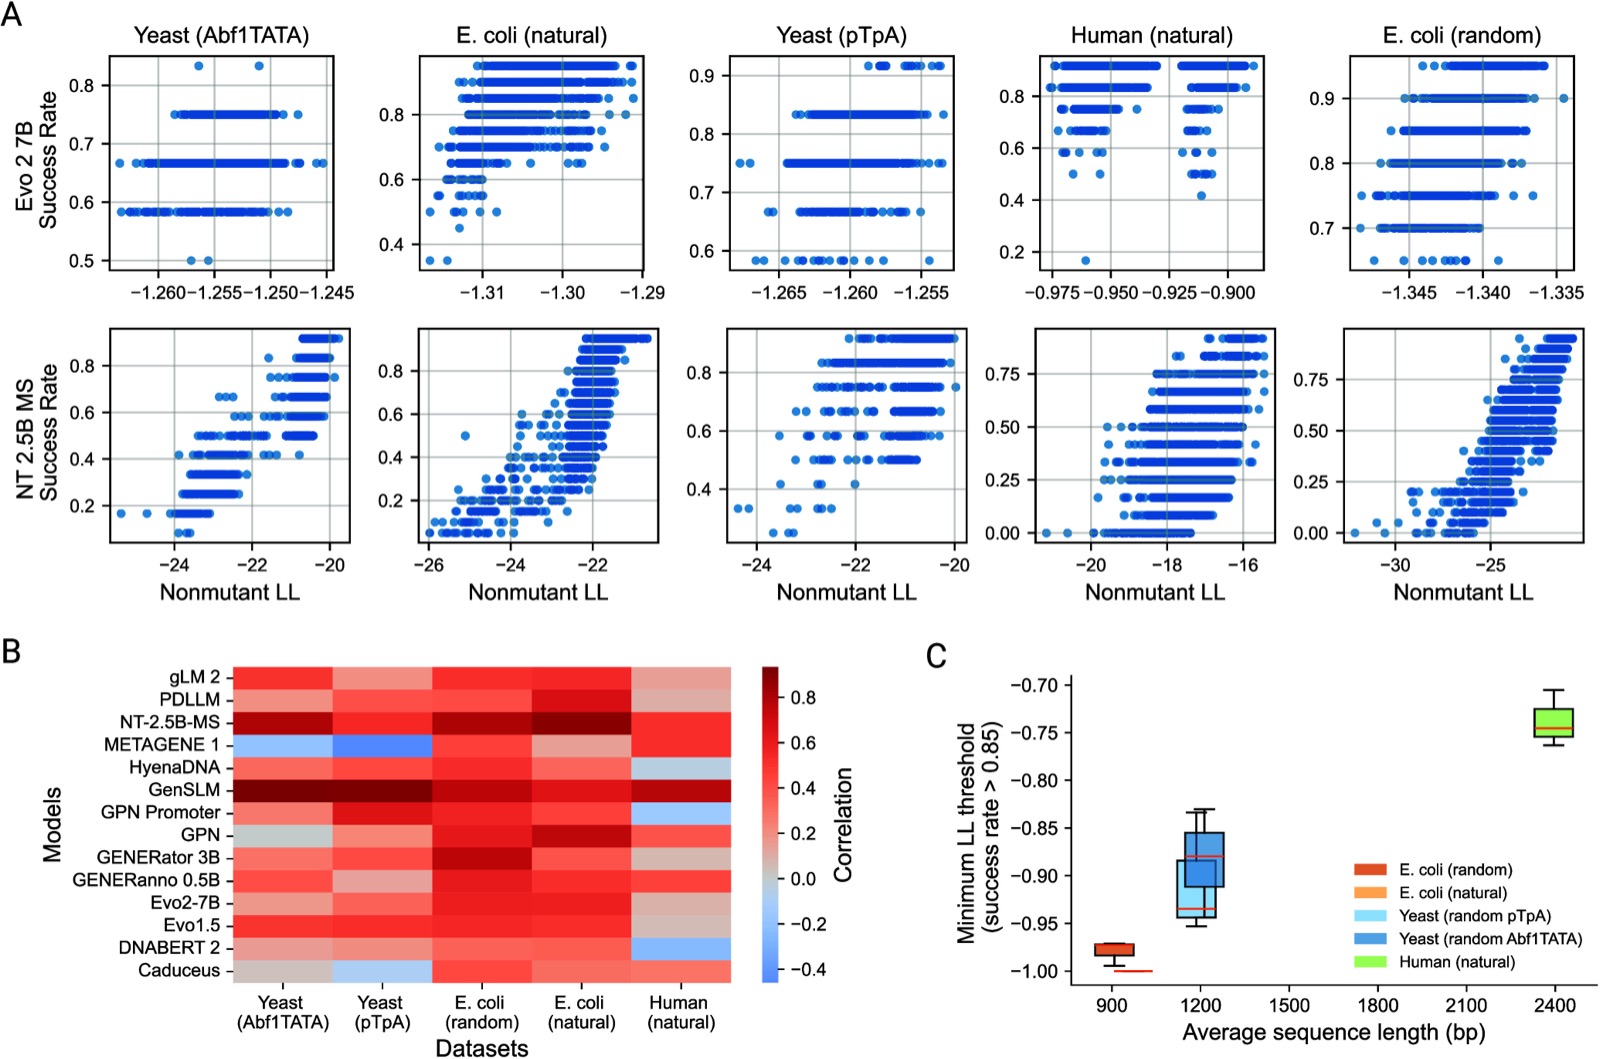
Figure 7. In the Nullsettes datasets, zero-shot mutation-effect accuracy degrades as the functional reference becomes less probable to the model. Figure 2 from Jiang et al. (2026), uniformly resized from 4,142 × 2,742 pixels to 1,600 × 1,059 pixels, with no crop or content change, licensed under CC BY 4.0.
Nullsettes is not an overall leaderboard, and its virtual constructs do not represent every natural-genome task. It falsifies a narrower inference within this benchmark: a construct designed to be nonfunctional under the benchmark's ordering rules can still receive a likelihood ordering that misses the disruption. Likelihood remains useful. The stress test tells us where the likelihood hypothesis breaks.
Run cheaper explanations under the same split. Include GC and k-mer features, one-hot sequence models, conservation, and a relevant supervised specialist. Add reverse-complement checks, distal-context ablations, and counterfactuals matched to the intended use. Report the simple model that wins.
Does “open” describe the artifact you need?
For this comparison, I treated papers, code repositories, checkpoints, prepared datasets, and hosted services as separate artifacts. The linked records were collected on 28 August and rechecked on 2 September 2026; licences, gates, and hardware paths can change.
| Family | Code | Checkpoint | Data or service | Practical boundary |
|---|---|---|---|---|
| Nucleotide Transformer v1/v2 | CC BY-NC-SA 4.0 | The inspected NT-v2 card uses the same licence | Check separately | A repository licence is not automatically a data licence |
| NTv3 | Repository and checkpoint terms differ | Auto-gated, license: other, with separate model terms |
Gate acceptance required | Do not inherit the code licence for the weights |
| HyenaDNA | Apache-2.0 | The selected Transformers-format 1M card declares BSD-3-Clause | Check separately | Code and weight licences differ |
| Caduceus | Apache-2.0 | Ph and PS cards declare Apache-2.0 | Check separately | Record the symmetry variant as well as the licence |
| GenNA | MIT | The official public weight record states no weight licence | Check separately | Public download alone does not establish reuse permission |
| DNABERT / DNABERT-2 | Public DNABERT and DNABERT-2 repositories | Named weights with separate DNABERT and DNABERT-2 records | Complete prepared corpora and rights require separate records | Runnable checkpoints do not make pretraining reconstructable |
| GENERator-v2 | MIT-labelled code | MIT-labelled eukaryotic weights | Named MIT-labelled pretraining data | Upstream source records retain their own terms |
| Evo 2 | Apache-2.0 | The inspected 7B card declares Apache-2.0 | OpenGenome2 declares Apache-2.0 | The official 1B, 20B, and 40B paths require FP8 on an NVIDIA Hopper GPU; 7B has a bfloat16 path |
| Borzoi | Apache-2.0 | Downloadable weights, with no separate weight licence on the inspected route | Large training bucket is requester-pays | “Weights downloadable” is supported; “Apache-licensed weights” is not |
| AlphaGenome | Apache-licensed research implementation | Gated weights under separate non-commercial terms | Hosted API has separate service terms | The peer-reviewed system is supervised sequence-to-function, and it is no longer hosted-only (Avsec et al., 2026) |
Three failures recur: assuming one licence propagates across neighbouring artifacts, treating a runnable checkpoint as a reconstructable training release, and equating download access with operational practicality.
Archive the exact repository commit, model-card revision, checkpoint checksum, tokenizer, dataset version, accepted gate terms, precision, device, runtime, and peak memory. Prefer precise conclusions: “local inference is possible,” “weights are downloadable after accepting terms,” or “the prepared corpus was not released.” Reserve “reproducible” for the particular result actually rerun.
Choose by the failure you cannot tolerate
Model selection should be able to reject every candidate.
- Write the estimand. Choose a conditional allele probability, causal likelihood, embedding, labelled prediction, functional track, or generated sequence. Do not use “effect” as the unit.
- Freeze the coordinate and input contract. Pin assembly, coordinate convention, alleles, strand transform, tokenizer, crop, padding, ambiguous bases, species metadata, and any alignment.
- Match the prior. Choose human-reference, population, related-species, broad multispecies, all-domain, alignment-conditioned, or annotation-conditioned training because it fits the proposed transfer.
- Separate learning regimes. Put untouched scoring, frozen probes, full fine-tuning, post-trained hybrids, and supervised specialists in different result rows.
- Build the split before tuning. Remove coordinate overlap and redundancy, then add homology, species, temporal, donor, or perturbation separation when the claim requires it.
- Run cheap and specialist baselines. Compare k-mer or one-hot models, conservation, and the relevant assay or evolutionary specialist under the same labels and split.
- Attack the result. Test the correctly transformed reverse complement, perturb distal context, vary layer and pooling, repeat seeds, and add an appropriate counterfactual or distribution shift.
- Clear the release. Resolve code, checkpoint, data, service terms, and compute before the expensive experiment begins.
Figure 8. Selection proceeds from a task-specific route through input, split, baseline, stress-test, artifact, and compute gates, with rejection as a valid result. Sources: GPN, GPN-MSA, Enformer, Borzoi, BEND, the unreviewed DART-Eval version 2 preprint, Feng et al., and Nullsettes.
Predeclare an output-specific stop condition. Reject an embedding advantage that disappears under a fixed head or homology-aware split. Where a versioned conservation score is applicable, reject a claimed zero-shot advantage that cannot beat it under the same variants, coverage, metric, and split; also reject a score that fails the counterfactual matching its intended use. Reject a functional-track gain that vanishes in the required cell type or under distal-context ablation.
Stop a generation claim at the validation boundary declared in advance. Sequence checks can support sequence-distribution or motif claims, and structural checks can support structural-plausibility claims; neither establishes biological function. Make a functional claim only when a relevant experimental assay validates that function.
This process may select a compact evolutionary scorer, a frozen encoder with a fixed probe, a supervised assay predictor, or an autoregressive generator. It may select a one-hot model. It may reject every available system. Those are useful outcomes.
From DNA to RNA
A credible genomic-model claim names the full system: assembly, tokenizer, strand rule, context, checkpoint, adaptation, endpoint, split, baselines, and shifts. Tensor size does not change that evidential standard.
A reference DNA window also does not determine which transcript is present in a particular cell and condition, which splice form survives, how bases are modified, what structure forms, or how long the molecule persists. Part 6 moves to RNA foundation models, where sequence remains the substrate but molecular state becomes part of the representation problem.
Revision note
23 September 2026: added worked assay questions, a measured reporter example, a result-level evidence table and a reproducible proposed context control in response to reader feedback. No new model inference or wet-lab experiment is claimed.
References
- Ji Y, Zhou Z, Liu H, Davuluri RV. DNABERT. Bioinformatics. 2021.
- Zhou Z, Ji Y, Li W, et al. DNABERT-2. ICLR. 2024.
- Dalla-Torre H, Gonzalez L, Mendoza-Revilla J, et al. Nucleotide Transformer. Nature Methods. 2025.
- Boshar S, Evans B, Tang Z, et al. Nucleotide Transformer v3. bioRxiv preprint. 2025.
- Nguyen E, Poli M, Durrant MG, et al. HyenaDNA. NeurIPS. 2023.
- Schiff Y, Kao C-H, Gokaslan A, et al. Caduceus. ICML. 2024.
- Nguyen E, Poli M, Durrant MG, et al. Evo. Science. 2024.
- Brixi G, Durrant MG, Ku J, et al. Evo 2. Nature. 2026.
- Li Q, Zhan Z, Feng S, et al. Functional In-Context Learning in Genomic Language Models. bioRxiv preprint. 2026.
- Shen Y, Cao G, Wu J, et al. GenNA. bioRxiv preprint. 2026.
- Benegas G, Batra SS, Song YS. GPN. PNAS. 2023.
- Benegas G, Albors C, Aw AJ, et al. GPN-MSA. Nature Biotechnology. 2025.
- Avsec Z, Agarwal V, Visentin D, et al. Enformer. Nature Methods. 2021.
- Linder J, Srivastava D, Yuan H, et al. Borzoi. Nature Genetics. 2025.
- Marin FI, Teufel F, Horlacher M, et al. BEND. ICLR. 2024.
- Patel A, Singhal A, Wang A, et al. DART-Eval. Unreviewed arXiv preprint, version 2. 2025.
- Feng H, Wu L, Zhao B, et al. Benchmarking DNA foundation models for genomic and genetic tasks. Nature Communications. 2025.
- Jiang S, Liu X, Wang ZJ. Evaluating DNA Function Understanding in Genomic Language Models Using Evolutionarily Implausible Sequences. ACS Synthetic Biology. 2026.
- Ma M. Reverse-Complement Consistency for DNA Language Models. Unreviewed arXiv preprint. 2025.
- Greco D, Rawlik K. Same model, better performance. arXiv preprint. 2025.
- Avsec Ž, Latysheva N, Cheng J, et al. Advancing regulatory variant effect prediction with AlphaGenome. Nature. 2026.
- DNABERT authors. DNABERT repository and DNA_bert_6 weight licence. Retrieved 2026-08-28.
- MAGICS Lab. DNABERT-2 repository and 117M weight licence. Retrieved 2026-08-28.
- InstaDeepAI. Nucleotide Transformer repository licence, NT-v2 500M multispecies card, NTv3 guide, NTv3 100M record, and NTv3 model terms. Retrieved 2026-08-28.
- HazyResearch and LongSafari. HyenaDNA code and 1M checkpoint card. Retrieved 2026-08-28.
- Kuleshov Group. Caduceus repository, Ph checkpoint, and PS checkpoint. Retrieved 2026-08-28.
- LongSafari. OpenGenome. Retrieved 2026-08-28.
- Arc Institute. Evo 2 repository, 7B checkpoint, and OpenGenome2. Retrieved 2026-08-28.
- GenerTeam. GENERator repository, v2 eukaryotic checkpoint, and eukaryotic pretraining data. Retrieved 2026-08-28.
- GenNA authors. GenNA repository and official checkpoint. Retrieved 2026-08-28.
- Song Lab. GPN-MSA documentation. Retrieved 2026-08-28.
- Google DeepMind. AlphaGenome research implementation, all-fold weights, model terms, and service terms. Retrieved 2026-08-28.
- Calico Life Sciences. Borzoi repository and weight-download script. Retrieved 2026-08-28.
- BEND authors. BEND benchmark repository. Retrieved 2026-08-28.
Help improve this article
Found an error or a better source? Leave a note here, or highlight a passage to comment on it.